TL;DR
We built three pieces of audit trail architecture for a regulated AI platform: a transactional outbox so an audit event can’t be silently lost between Postgres and Redpanda, an OPA bundle server so a policy change doesn’t need a container restart, and effective_from / effective_to temporal tables so nothing that matters for compliance ever gets overwritten. None of the three were hard to design. All three were easy to half-build and declare done. Here’s what we did, what the first attempt at each one taught us, and what we’d still change.
Previous: Red-Teaming AI: OWASP LLM Top 10 and the Probes You Actually Need | Next: Human-in-the-Loop Is an Architecture Decision, Not a Feature
🏗️ What We Built
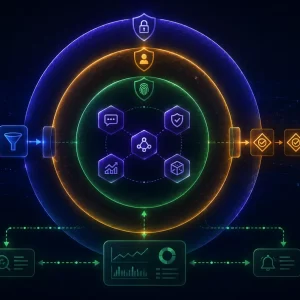
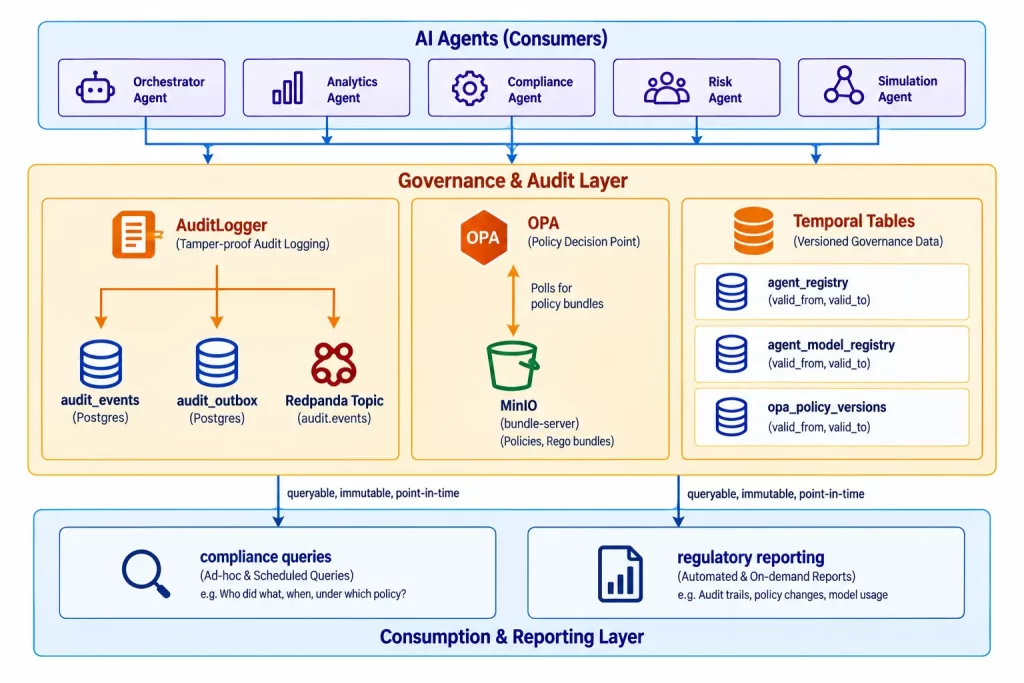
A regulated AI platform needs to answer one question years after the fact: what happened, under whose authority, and can you prove it. We built the infrastructure for that answer in three layers.
The first layer is an audit trail that survives a crash between writing to Postgres and publishing to the event stream — the AuditLogger plus a transactional outbox. The second is a policy layer that can change a threshold in thirty seconds instead of a rebuild — OPA reading policy bundles from MinIO instead of a mounted file. The third is configuration history that never loses a value once it’s been true: agent_registry, agent_model_registry, and opa_policy_versions, all append-only.
Each of these three went through an earlier design before we arrived at what’s below, and a couple of those earlier choices are worth knowing because they explain why the final version looks the way it does — the same design-iteration process we walked through in The 57-Gap Audit. This article is about that final version and why it holds up, not a tour of the drafts that came before it.
Back to top . Next: The Audit Trail We Actually Needed →
📝 The Audit Trail We Actually Needed
A log line and an audit event look similar in code. They are not the same thing, and mixing them up is what cost us three weeks.
A log line is operational. It’s useful for debugging and it’s fine that Loki keeps ours for 30 days. An audit event has to answer a regulatory question years later — which agent made this credit decision, what fatwa supported that Sharia ruling — so it needs to be immutable, timestamped, attributed, and queryable long after anyone remembers writing it.
Retention requirements vary by regulator but not by much: CBUAE, SAMA, and AAOIFI want 7 years for credit decisions and indefinite retention for Sharia records. A 30-day Loki log satisfies none of it.
What Went In First
AuditLogger was wired into all five agent services early on. It called structlog.info() and returned. The INSERT INTO audit_events that was supposed to follow never got written, so for weeks the dashboards showed activity and the table sat at zero rows. Nobody caught it in review, because the class existed, the method was called, and the schema was correct — everything a code reviewer normally checks.
A fire-and-forget _persist_to_db() call fixed the missing rows. It also exposed a second problem we hadn’t designed for: a SIEM, OpenMetadata, and a reporting dashboard all needed these events on a Redpanda topic too, and writing to Postgres then publishing separately means anything that fails between the two calls loses the event for good.
The Outbox
The fix is a standard distributed-systems pattern, not something we invented: a second table, audit_outbox, in the same database as audit_events. One local Postgres transaction writes both rows, so there’s no external coordinator and no window where one write succeeds and the other doesn’t.
- Atomic write: one transaction writes to
audit_eventsandaudit_outboxtogether — both succeed or both fail. - Background polling: a poller runs every two seconds, publishes unpublished rows to Redpanda’s
audit.eventstopic, marks them published. - Guaranteed delivery: if the poller crashes mid-publish, the row stays unpublished and goes out next cycle.
I’ll say plainly what I think the rule should be, because it’s the one thing from this section worth remembering on its own: writing an audit event to a database and separately publishing it to a stream is not the same as writing it once, atomically, to both. The first is two operations that can disagree. The second is one operation that can’t.
Keeping the Table From Growing Forever
We asked ourselves this once the outbox was actually working: 7-year retention on audit_events, indefinite for Sharia rows, and the table never deletes anything by design. Left alone, that’s an unbounded write-heavy table with no ceiling.
The decision we landed on has three parts. Partition audit_events by month, so a query for last week’s decisions never has to scan years of history. Once a partition falls outside the window anyone actually queries in practice, archive it to MinIO as compressed, still-queryable cold storage — the record is retained exactly as long as CBUAE and AAOIFI require, it just isn’t sitting in the hot table anymore. And prune audit_outbox a short grace period after a row is marked published, because the outbox is a delivery queue, not the compliance record — once Redpanda has the event, that row has done its job.
That last distinction is the actual learning here: audit_events and audit_outbox look like the same kind of table because they’re written in the same transaction, but they answer different questions. One has to survive for years. The other only has to survive until Redpanda confirms delivery. Treating them identically is how you end up over-retaining a queue.
What I’d recommend to anyone starting this fresh: decide the partition key before the first row is written, not after the table has a primary key and other tables pointing foreign keys at it. Retrofitting a partition key onto a live, referenced table is a real migration — it touches the primary key and everything that references it — where deciding it upfront costs nothing.
Back to top . Next: Policy-as-Code, Without the Restart →
⚙️ Policy-as-Code, Without the Restart
We covered getting authentication and authorization onto every agent earlier in this series with Open Policy Agent (OPA) as the decision point. What that version didn’t solve: changing a threshold meant editing a file, rebuilding the container, and restarting OPA — so thresholds mostly didn’t get updated.
Four things followed from that setup, and none of them showed up until an audit forced the question. Changing policy meant a redeploy, so it happened rarely. There was no record of when a running container actually picked up a change — Git shows when the file changed, not when the restart took effect. Enforcement was partial: Sharia, Risk, Simulation, and the Orchestrator never called OPA at all, so a request could reach the Sharia agent with no authorization check whatsoever. And because policy shipped bundled with agent code, updates that had nothing to do with logic still triggered a full deployment.
One decision we made early and never revisited: Rego policies default to allow := false. It’s a small rule with a large effect — default-allow turns a missing rule into a silent grant, and we didn’t want that failure mode available at all, even by accident. Each agent gets back more than allow or deny — whether HITL is required, whether a Sharia evaluation must run first, whether the tier should change. Python never makes that call. OPA does.
Reading From an Object Store Instead of a File
The fix: package policies as a compressed bundle, upload it to MinIO — self-hosted, S3-compatible — and have OPA poll for it every 30 seconds, activating any bundle with a newer ETag. No restart, no redeploy.
Each bundle holds two files: authz.rego for the rules, data.json for the tier map. A shell script, bundle.sh, packages them for atomic activation and checks that OpenBao is reachable with a valid deploy token before it uploads anything. We got that check wrong the first time. An unreachable OpenBao made the token check return an empty string, which was accidentally truthy in the script’s logic, so it deployed anyway — a fail-open bug in exactly the place we couldn’t afford one. We rewrote it so any validation failure is fatal, full stop.
One more gap we found later, doing an unrelated review: OPA’s own allow/deny decisions weren’t being recorded anywhere. OPAClient.evaluate() did a debug log and nothing else — the audit event type for it, POLICY_EVALUATED, had been sitting unused in the enum the whole time. We wired it up to write through the same outbox path as everything else. It’s a reminder that “audit everything” has to be checked component by component, not assumed once you’ve built the pattern.
Back to top . Next: Dual-Control for Policy Changes →
🔐 Dual-Control for Policy Changes
Hot reload solves the deployment problem. It opens an accountability one: if anyone with access to bundle.sh can push a policy in thirty seconds, speed has outrun oversight.
The first control is ordinary GitOps. authz.rego lives in version control, changes need a pull request, and CODEOWNERS requires both the compliance officer and the security lead to review — neither can approve their own change. That covers what gets merged. It doesn’t cover what gets deployed, and merging a change plus running bundle.sh are two different actions that the same developer could still do alone.
So the second control is a governed deploy endpoint, gated behind an admin key separate from the normal agent API key, stored in OpenBao, rotated quarterly, logged on every use. Merging a change doesn’t activate it. Every deployment also writes a row to opa_policy_versions — who deployed it, why, and an effective_from / effective_to pair — so “what policy was active at time T” always has an answer. For an Islamic finance platform this gives the Sharia Board a real, blocking role in technical governance: rules about which products need Sharia pre-approval go through the same review as any other policy change.
A CI workflow later used to deploy OPA bundles with the MinIO root credentials, which is the kind of shortcut that’s easy to justify in the moment and hard to defend afterward. We gave it its own scoped identity, limited to that one bucket, and moved on.
Back to top . Next: Why We Stopped Using UPDATE →
🕰️ Why We Stopped Using UPDATE
Every engineer who’s built databases professionally has the same reflex: when data changes, you update the row. It’s correct for most systems. We learned, the expensive way, that it’s a liability in this one.
Here’s the scenario that changed our minds. The Sharia agent starts at SUPERVISED. Three weeks later someone promotes it to FULL, and the instinct is UPDATE agent_registry SET autonomy_tier = 'FULL' WHERE agent_name = 'agent-sharia'. Correct, right up until a CBUAE examiner asks what tier the agent was operating under for a transaction approved on 14 March at 09:47. The row says FULL, because that’s what’s true now. What was true on 14 March is gone. The UPDATE erased it, and there’s no getting it back.
Every configuration change, model version change, and policy change has to be a new row with a timestamp — not an edit to an old one. That’s the whole rule, and SR 11-7, the CBUAE Model Risk Guidelines, and AAOIFI Governance Standard 6 all assume it in their own language.
Soft-Close and Insert
Every row carries effective_from and effective_to (NULL means current). One transaction does two things: soft-close the current row with SET effective_to = now() WHERE effective_to IS NULL — the only UPDATE we allow anywhere in this design, and it only ever stamps an end date — then insert a new row with the new value, a fresh effective_from, and who approved it.
| agent_name | autonomy_tier | effective_from | effective_to | tier_changed_by |
|---|---|---|---|---|
| agent-sharia | SUPERVISED | 2026-02-01 08:00:00+00 | 2026-03-14 11:22:00+00 | NULL (self-registered) |
| agent-sharia | FULL | 2026-03-14 11:22:00+00 | NULL (active) | alice@bank.ae |
Query at 09:47 with effective_from <= T AND (effective_to IS NULL OR effective_to > T) and you get SUPERVISED. The promotion happened at 11:22, after the decision the examiner cares about. Nothing gets deleted or overwritten. The table only grows, and it’s its own audit trail.
Not everything needs this treatment — caches and session state can still be overwritten freely. Four tables carry the rule because they govern decisions, policies, models, and audit events: agent_registry, agent_model_registry, opa_policy_versions, and audit_outbox, where the only permitted post-insert change is marking a row published.
Back to top . Next: Point-in-Time Reconstruction →
⏱️ Point-in-Time Reconstruction
This is the payoff. A customer disputes a Murabaha offer from 14 March 2026, 09:47 UTC, and the regulator wants the full picture: which model ran, under which policy, at which agent tier, with what audit trail. With the outbox and the temporal tables in place, that’s four queries against the same timestamp.
- Model version:
agent_model_registryat 09:47 →v1.2, approved by Alice on 1 February. - Autonomy tier:
agent_registry, same timestamp →SUPERVISED, the tier before that morning’s promotion. - Active policy:
opa_policy_versions→ bundleauthz/bundles/2026-02-15.tar.gz, downloadable and inspectable. - Audit trail:
audit_eventsfor that task ID → the full sequence, timestamped and attributed.
Skip the temporal design and at least one of those four queries returns today’s state instead of March’s. The reconstruction is just wrong, and there’s no way to tell from the output alone. The same tables pay off outside audits, too — compliance officers can query them directly instead of opening a ticket, and root-cause work gets faster.
On GDPR right-to-erasure: it’s compatible with immutability. We pseudonymise instead of deleting — replace customer_id with a hash derived from a deleted-customer salt. The record survives. The link to a real person doesn’t.
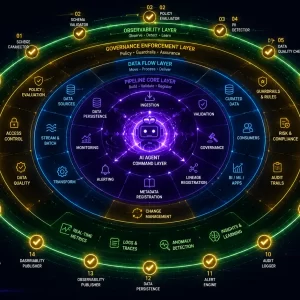
Put together, a single credit decision produces a connected chain, all linked by one task ID: a decision trace, the audit events in the outbox stream, the Sharia decision detail with fatwas cited, the full trace of every LLM call, and the exact policy and model context that was active at the time.
Compliance Infrastructure Stack
AuditLogger
Dual-writes to audit_events + audit_outbox in one transaction. Fire-and-forget.
Transactional Outbox
Polled every 2 seconds, exactly-once delivery to Redpanda. Survives a poller crash.
OPA + Rego
Deny-by-default across all five agents. Python never makes the call.
MinIO Bundle Server
OPA polls every 30 seconds. Policy updates without a restart.
CODEOWNERS + Deploy API
Two gates: mandatory PR review, then an admin-key-gated deploy endpoint.
opa_policy_versions
Append-only. Returns the exact policy active at any past timestamp.
agent_model_registry / agent_registry
Temporal model-version and tier history with four-eyes metadata.
Debezium CDC
Streams raw Postgres changes to Redpanda for lineage tools.
Back to top . Next: What We’d Still Change →
🧭 What We’d Still Change
Three things, if I’m honest, and none of them are load-bearing today — which is exactly why they’re easy to leave for later, and exactly why I’m writing them down.
authz.rego has zero automated test coverage right now. That’s very plausibly how the deny-rule wiring bug above went unnoticed for as long as it did — a regression test for that exact bug would have failed until we fixed it, and we don’t have one yet. MinIO’s buckets, including the one holding policy bundles, have no versioning, lifecycle policy, or object lock, so retention depends entirely on a scheduled job with no independent protection against an accidental delete. And Debezium, which streams the raw Postgres changes behind these tables to Redpanda for lineage tools, has no dead-letter queue — a failed CDC event is only visible in container logs, not durably captured anywhere.
None of these three break the audit trail, the policy layer, or the temporal tables as designed. They’re the next layer of insurance around them, and they’re the honest answer if you ask what I’d do with another sprint.
Back to top . Next: Key Takeaways →
Key Takeaways
- A wired-up class or a mounted policy file tells you what was intended, not what happens. We only trusted the rows once we’d counted them ourselves.
- Static policy is policy-in-code, not policy-as-code — a bundle server plus dual-control (GitOps review and a separately-credentialed deploy API) is the minimum we’d consider shipping for a regulated system.
- UPDATE is the enemy of compliance — soft-close and insert is the only pattern that answers “what was true at time T,” which is what a regulator eventually asks.
Connect With Me
- LinkedIn: Connect on LinkedIn
- GitHub: github.com/neerajg5
- Blog: learnwithneeraj.com
Enjoyed this article?
Get notified when the next one is published.
We send one email per new article — no spam, unsubscribe any time.
⚠️ Disclaimer: The information provided on LearnWithNeeraj.com regarding Astrology, Numerology, and other topics is for educational and guidance purposes only.
Not Professional Advice: This content should not be used as a substitute for professional medical, legal, or financial advice. Always consult a certified professional for specific concerns.
Guest Authors: This site features articles by various contributors. The views and interpretations expressed are those of the individual authors and do not necessarily reflect the views of the website administrator.
Your destiny is in your hands. Use this information as a map, not a mandate.